Work · Fintech · AI agent
Reps spend 30 minutes digging before every reply
What I built: An AI that reads the history and drafts the reply
Before a rep replies, the AI reads the CRM, email, LinkedIn chat and call notes, then drafts the reply. A person still checks and sends. Saves 30+ min per contact (self-reported).
Same client as the other fintech examples.
30+ min saved per contact (self-reported)
30+ min saved per contact (self-reported) ~80% less context work (self-reported)
Verified = seen in the system. Self-reported = my own measure.
30 minutes of digging before every reply.
A good reply needs context: the last call, the last email, the LinkedIn thread, the deal stage.
That context lived in four places. Reps spent 30+ minutes pulling it together before they could write one line.
One assistant reads it all first.
- A Reply Assistant in n8n. Ask it in chat, or call it from the CRM over an API.
- It pulls the CRM record, the Outlook thread, the LinkedIn conversation and the meeting summaries.
- NVIDIA Nemotron (via NIM) writes a short brief first, then a draft reply. A person reviews and sends.
- A meeting-ingest workflow keeps the assistant’s meeting notes current.
- Inside the CRM, the built-in AI chat answers “summarise this person” with a snapshot, key points and a suggested reply.
Step by step
- A rep asks for a reply in chat, or clicks from the CRM.
- n8n pulls the CRM record, the Outlook thread (Microsoft Graph), the HeyReach LinkedIn chat and the meeting notes.
- Nemotron writes a short brief on the contact.
- Nemotron writes the draft reply from that brief.
- The rep edits and sends. Nothing goes out on its own.
Screenshots
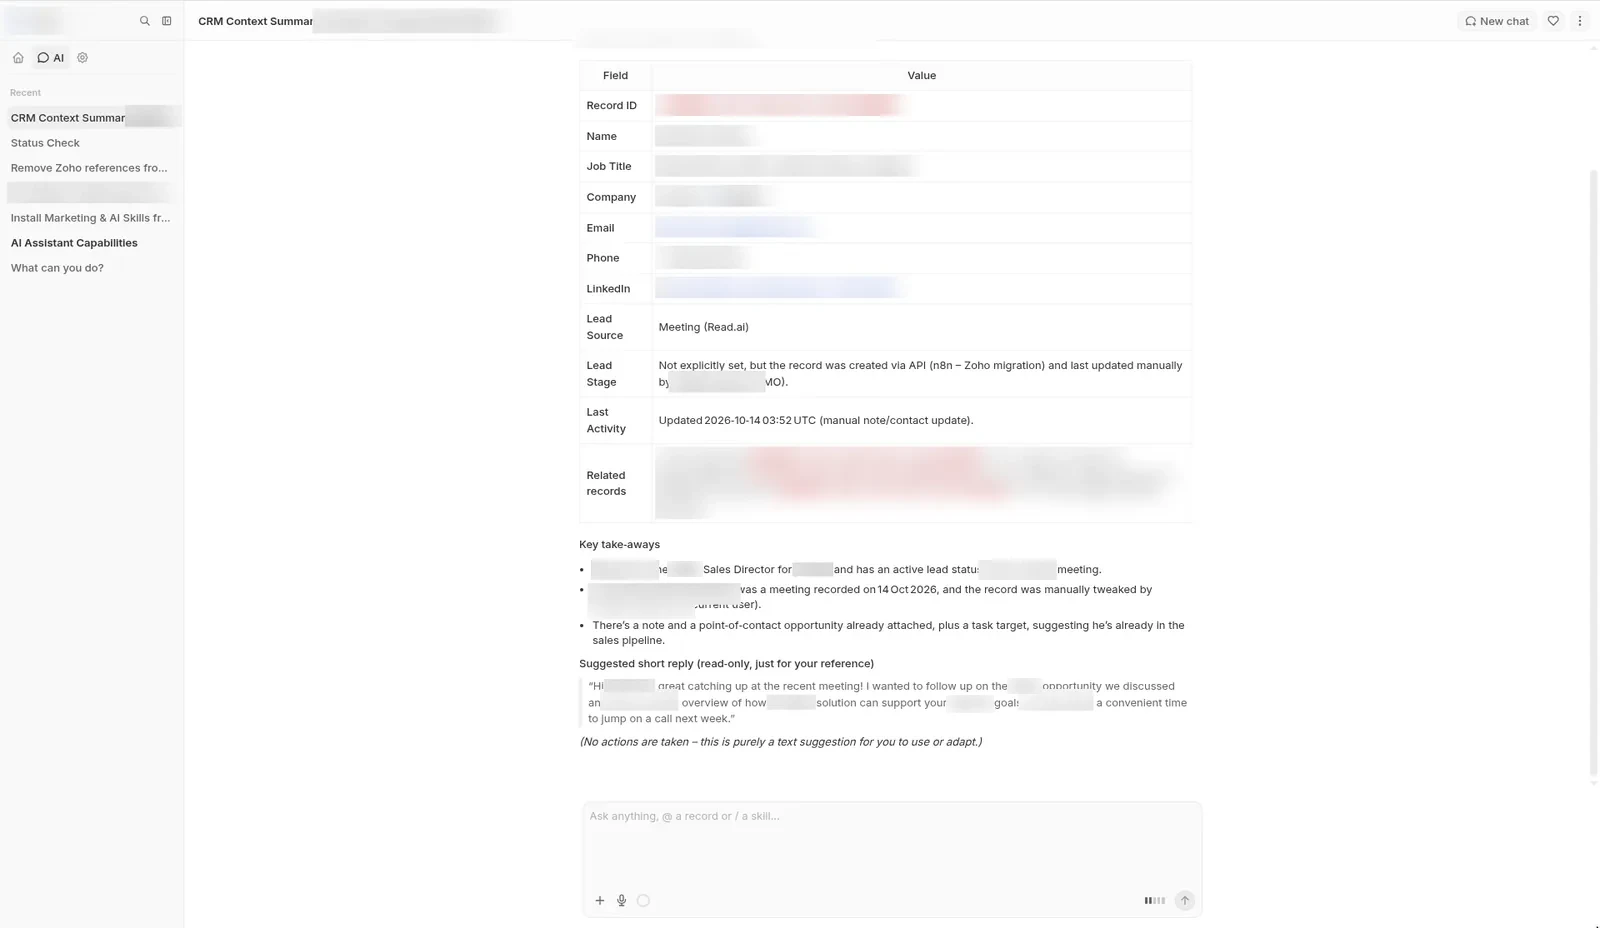 The CRM’s AI chat summarising a contact.
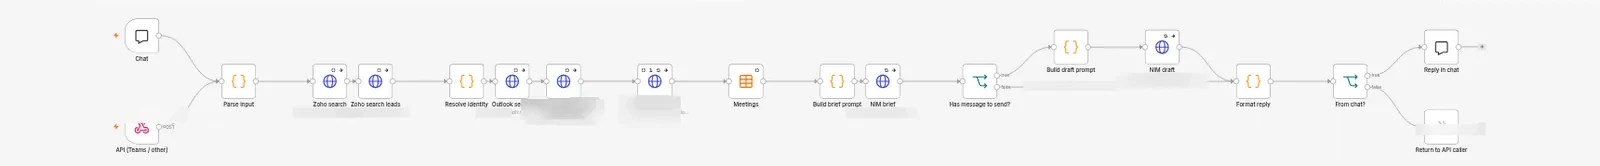 The Reply Assistant in n8n.
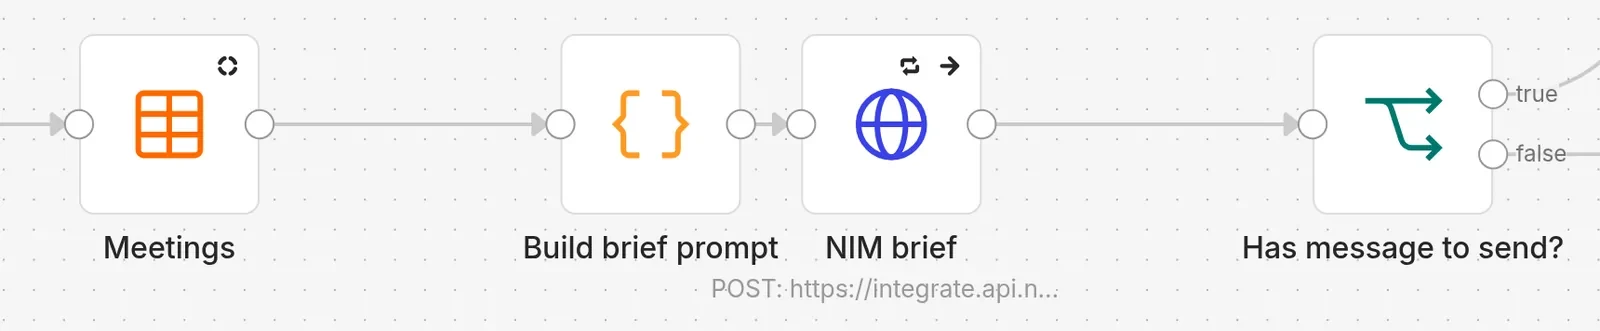 Two Nemotron calls: brief first, then the draft.
How I built it
- I worked inside the team’s own tools: their self-hosted n8n and their self-hosted Twenty CRM.
- I wrote the workflows with Claude Code as my AI coding tool (self-reported). I decided what to build and checked every run.
- Read-only probe workflows tested each API before anything wrote to it.
What you can check
- Verified: The full flow runs in n8n: chat and API triggers, then CRM, Outlook, HeyReach and meetings, then a Nemotron brief and a Nemotron draft. Source: n8n workflow, 15 Oct 2026
- Self-reported: Saves at least 30 minutes per contact and cuts about 80% of the manual work of pulling context. Source: Reported by Rukesh
Take the workflow, free
- AI reply assistant (contact brief + draft reply): AI writes a contact brief and a draft reply. A person sends it.
What this means for your team
Your reps stop digging and start replying. The AI reads everything first, and a person still presses send.
Tools
- n8n
- NVIDIA Nemotron (NIM)
- Twenty CRM
- Outlook / Microsoft Graph
- HeyReach
- Read.ai